The Work a Verifier Needs
A certified int8 output head picks the same token as the engine’s, recomputing about 1.8 vocabulary entries per decision.
On one GH200, Qwen3.5-4B throughput rises 1.3–4.6% over tuned stock SGLang at one request, and the fastest setup is 1.0–3.0% slower at 2 to 8 requests at once. The guarantee assumes a tested but unproved error model of the production kernel.
Details
An int8 copy of the LM head bounds every vocabulary score. The head recomputes only the entries that could win and falls back to the engine’s head when the bounds leave the token undecided.
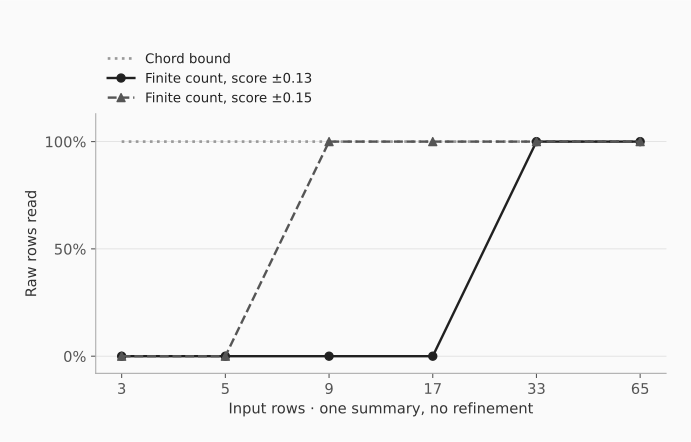
Every token matches the engine head on the same batch in replay and when served beside the stock head. Drafter-head bounds skip almost no vocabulary in the tested variants.
The certification theorem assumes a tested but unproved error model of the closed-source production kernel.